TL;DR
A cloud backup is only useful if the business can recover the data from it. This article breaks down what makes backup data genuinely recoverable and how businesses can build a data protection strategy around those requirements.
A backup can be complete, stored safely, and still leave a business unprepared for recovery.
The real question is whether the data inside that backup is complete, accessible, and usable when the business needs it.
The numbers show the distinction clearly. Sophos’ 2026 State of Ransomware report found that 66% of businesses whose data was encrypted used backups to recover it, an increase of 12 percentage points from 2025. Backups remain one of the main recovery methods, but the fact that not all businesses rely on their backups shows that having a backup system in place does not automatically make recovery straightforward.
Recoverability starts with what gets backed up. Files may need their permissions, metadata, folder structure, and previous versions preserved, where supported by the source platform. The backup also needs enough backup retention to provide a usable restore point, enough automation to keep that restore point current, and independent storage that remains available if the primary environment is compromised.
In this article, we’ll look at what makes cloud backup data recoverable, which parts of a backup strategy matter most, and how businesses can build data protection around recovery rather than storing another copy of their data.
What Makes Backup Data Recoverable?
A recoverable backup must be accompanied by a recovery process, and the recovery process must work when the business needs it.
Several parts of a cloud backup strategy determine whether a backup is genuinely usable.
1. The Right Data Is Backed Up
Recovery starts with coverage.
If important folders, files, versions, or business data are excluded from the backup, they cannot be recovered later. Backup policies should therefore define what needs to be protected rather than backing up whatever is easiest to configure.
This is particularly important for businesses working across multiple SaaS platforms, where data can be spread across different users, folders, projects, and services.
2. Permissions and Metadata Are Preserved
Recovering a file is not enough.
Business data often depends on the information around the file, such as its permissions, metadata, folder structure, and versions. If those elements are missing after a restore, the business may have to spend additional time rebuilding the environment manually.
A recoverable backup should preserve the information needed to make restored data usable.
3. Backup Retention Matches Recovery Needs
Retention should reflect how far back a business may need to recover.
This is where Recovery Point Objective (RPO) and Recovery Time Objective (RTO) matter. RPO defines how much recent data the business can afford to lose, while RTO defines how quickly it needs to restore operations. Together, they help determine how frequently backups should run and how long recovery points should be retained.
Retention should also be reviewed as business requirements change.
4. Backups Run Automatically
A recoverable backup needs to stay current.
Manual backups introduce a simple problem: someone has to remember to run them. If a backup is missed, the most recent recovery point may be older than expected.
Automated scheduling removes that dependency. Daily, weekly, or more frequent backups can keep recovery points current without adding another task to the IT team’s workload.
5. Backup Data Is Stored Independently
Where the backup lives makes a huge difference.
If backup data remains inside the same environment as the production data, the same incident could potentially affect both. CISA recommends maintaining backups separately and regularly testing their availability and integrity, particularly in the context of ransomware recovery.
Customer-controlled storage provides another layer of independence. The business can maintain its backup data in a destination it controls rather than relying entirely on the same environment that contains the original data.
6. Recovery Has Been Tested
This is where a backup becomes more than an assumption.
AWS recommends periodically recovering data from backups to verify that it can actually be restored, that the restored data is complete and accessible, and that recovery can meet the business’s defined objectives.
Testing doesn’t need to mean restoring everything every time. Businesses can define recovery scenarios, select representative data, restore it to a separate location, and verify that the result is usable.
The important point is simple: don’t wait for an incident to discover whether the restore process works.
How Cloudsfer Helps Make Backup Data Recoverable
Cloudsfer brings several of these capabilities together in its cloud backup solution.
- Configurable retention policies allow businesses to define how long backup data should remain available based on their recovery requirements.
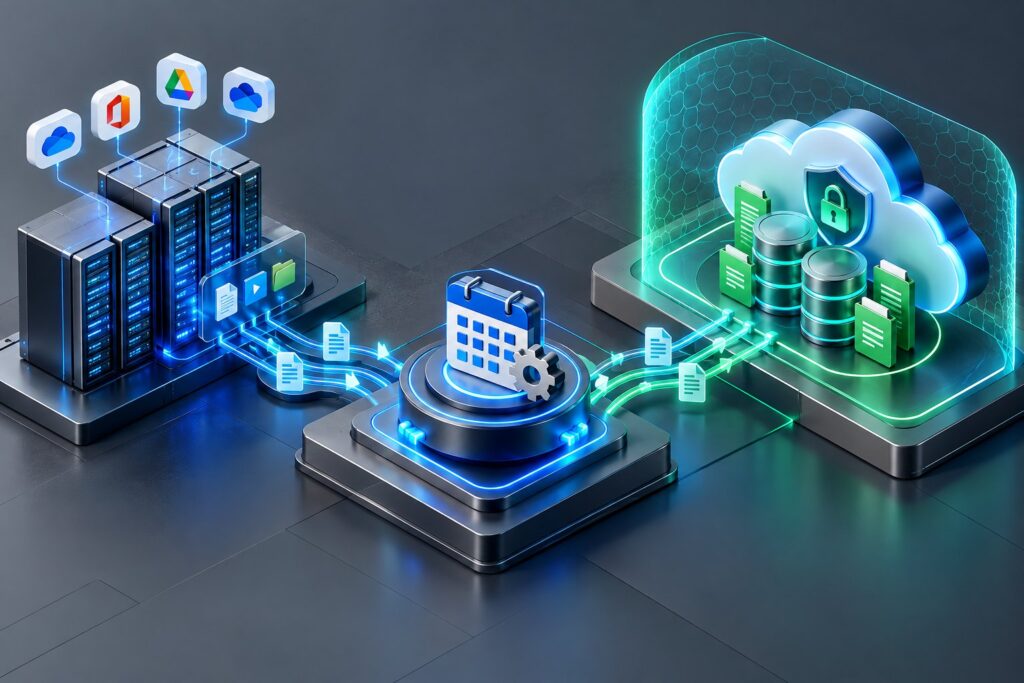
- Automated scheduling with Set & Forget runs backups on a schedule defined by the business, helping keep recovery points current without manual intervention.
- BYOS — Bring Your Own Storage sends backup data directly to destinations the business owns and controls, including Amazon S3, Azure Blob Storage, and other supported targets. This keeps backup data independent from the source environment.
- Permissions and metadata preservation help maintain the information around business files so restored data remains useful and organized.
- Incremental backups transfer only new or modified data after the initial backup, helping keep recurring backup jobs efficient as data volumes grow.
- Restore capabilities allow businesses to recover protected data when files or folders need to be restored after accidental deletion, data loss, or another recovery event.
Closing the Recoverability Gap
A backup is successful when the business can find the right recovery point, restore the required data, and use that data when it matters.
That requires the right coverage, preserved context, appropriate backup retention, automated protection, independent storage, and a recovery process that has been validated.
Building those elements into a cloud backup strategy turns backup from a stored copy into something the business can rely on.
Frequently Asked Questions
1. What makes a cloud backup recoverable?
The backup needs complete data, preserved permissions and metadata, appropriate retention, independent storage, and a restore process that works.
2. Why is backup retention important?
Retention determines how far back a business can recover when older data is needed.
3. Why should backups be stored independently?
Independent storage helps protect backup data if the primary environment is compromised.
4. Is restore testing necessary?
Yes. Testing verifies that backup data can actually be restored and used when recovery is required.
5. How does Cloudsfer support recoverable backups?
Cloudsfer provides automated scheduling, configurable retention, BYOS, incremental backups, permissions and metadata preservation where supported by the source platform, and restore capabilities.